


Write mJev-Qwen3-VL-4B-RLCD model card
Browse files
README.md
CHANGED
|
@@ -1,204 +1,111 @@
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
| 3 |
-
pipeline_tag: image-text-to-text
|
| 4 |
library_name: transformers
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
---
|
| 6 |
-
<a href="https://chat.qwenlm.ai/" target="_blank" style="margin: 2px;">
|
| 7 |
-
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
|
| 8 |
-
</a>
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
# mJev
|
| 12 |
-
|
| 13 |
-
mJev is a Jev-style multimodal decision model based on Qwen3-VL-4B-Instruct.
|
| 14 |
-
It turns multimodal context into explicit choices with candidate probabilities.
|
| 15 |
-
|
| 16 |
-
## Base model
|
| 17 |
-
|
| 18 |
-
- Architecture: Qwen3-VL-4B-Instruct
|
| 19 |
-
- Task: Multimodal probabilistic decision making
|
| 20 |
-
|
| 21 |
-
The architecture, loading method, and usage examples below follow the base model.
|
| 22 |
-
|
| 23 |
-
## About Qwen3-VL
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.
|
| 27 |
-
|
| 28 |
-
This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.
|
| 29 |
-
|
| 30 |
-
Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
#### Key Enhancements:
|
| 34 |
-
|
| 35 |
-
* **Visual Agent**: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.
|
| 36 |
-
|
| 37 |
-
* **Visual Coding Boost**: Generates Draw.io/HTML/CSS/JS from images/videos.
|
| 38 |
-
|
| 39 |
-
* **Advanced Spatial Perception**: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.
|
| 40 |
-
|
| 41 |
-
* **Long Context & Video Understanding**: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.
|
| 42 |
-
|
| 43 |
-
* **Enhanced Multimodal Reasoning**: Excels in STEM/Math—causal analysis and logical, evidence-based answers.
|
| 44 |
-
|
| 45 |
-
* **Upgraded Visual Recognition**: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.
|
| 46 |
-
|
| 47 |
-
* **Expanded OCR**: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.
|
| 48 |
|
| 49 |
-
|
| 50 |
|
|
|
|
| 51 |
|
| 52 |
-
|
| 53 |
|
| 54 |
-
|
| 55 |
-
<img src="https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/qwen3vl_arc.jpg" width="80%"/>
|
| 56 |
-
<p>
|
| 57 |
|
|
|
|
| 58 |
|
| 59 |
-
|
| 60 |
|
| 61 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 62 |
|
| 63 |
-
|
| 64 |
|
| 65 |
-
|
| 66 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 67 |
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
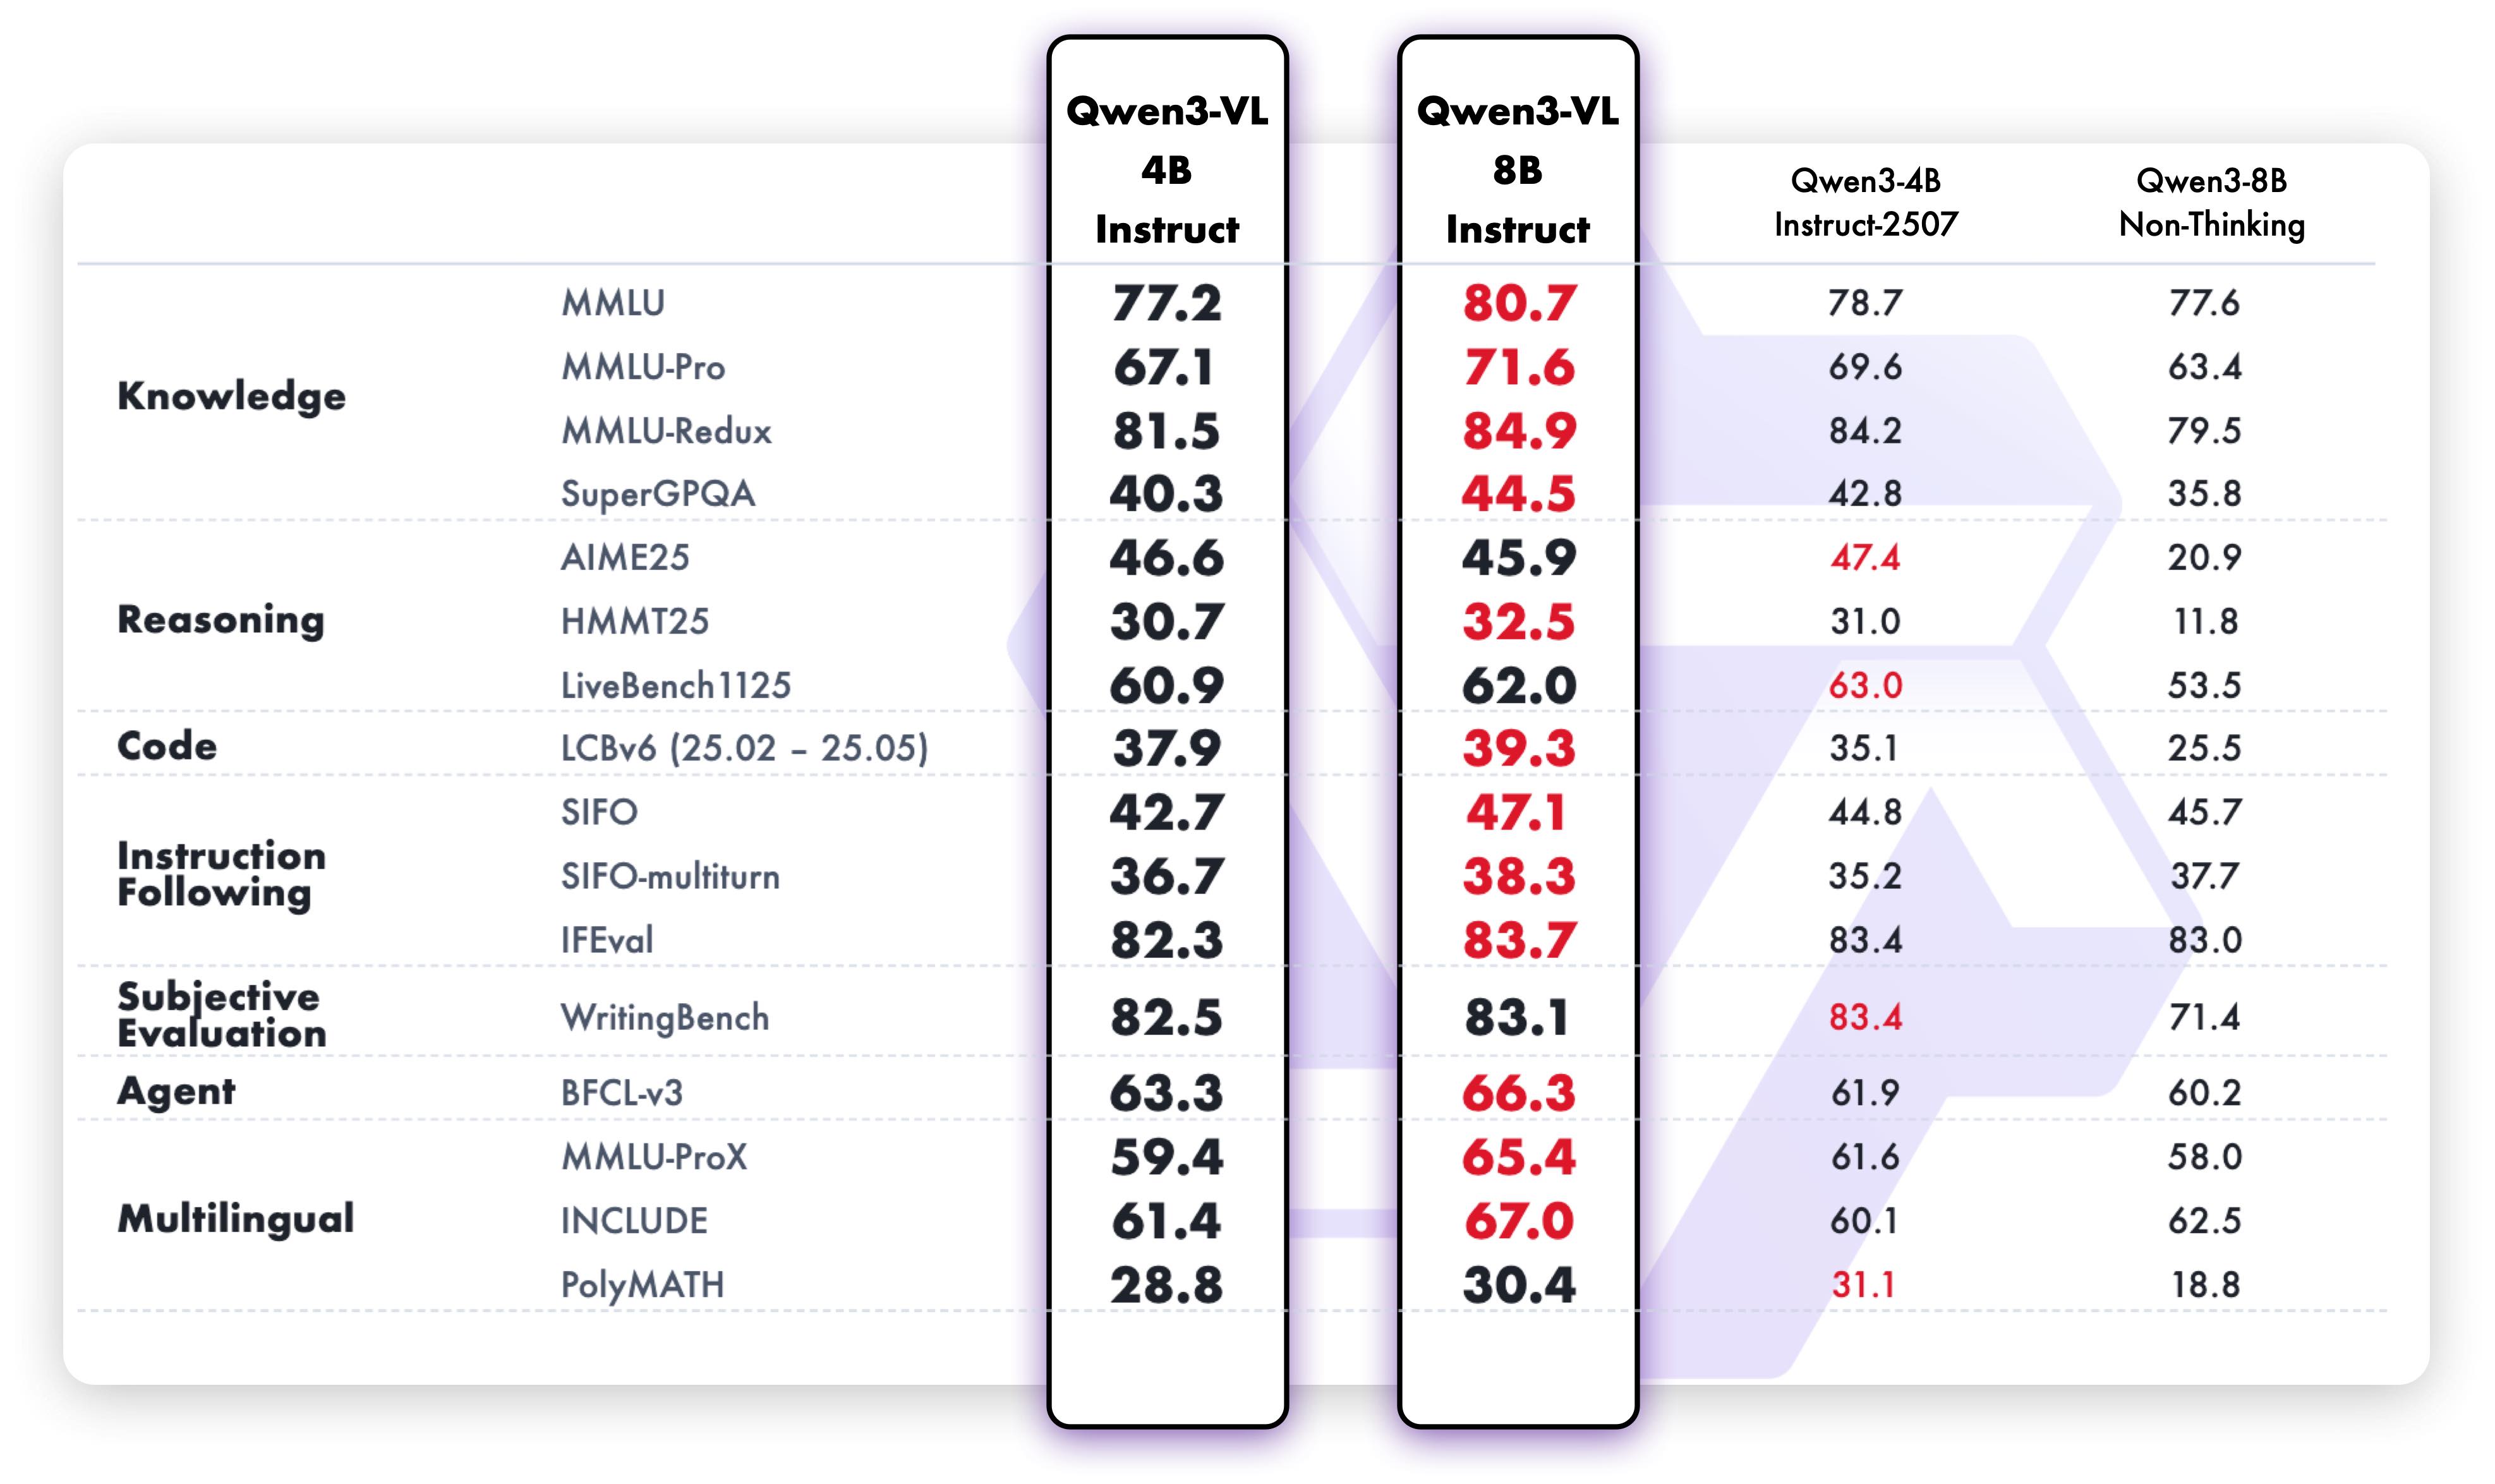
## Model Performance
|
| 71 |
-
|
| 72 |
-
**Multimodal performance**
|
| 73 |
|
| 74 |
-
|
| 75 |
|
| 76 |
-
|
| 77 |
-
|
| 78 |
|
| 79 |
-
|
| 80 |
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 87 |
```
|
| 88 |
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
Here we show a code snippet to show how to use the chat model with `transformers`:
|
| 92 |
-
|
| 93 |
-
```python
|
| 94 |
-
from transformers import Qwen3VLForConditionalGeneration, AutoProcessor
|
| 95 |
-
|
| 96 |
-
# default: Load the model on the available device(s)
|
| 97 |
-
model = Qwen3VLForConditionalGeneration.from_pretrained(
|
| 98 |
-
"Qwen/Qwen3-VL-4B-Instruct", dtype="auto", device_map="auto"
|
| 99 |
-
)
|
| 100 |
-
|
| 101 |
-
# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
|
| 102 |
-
# model = Qwen3VLForConditionalGeneration.from_pretrained(
|
| 103 |
-
# "Qwen/Qwen3-VL-4B-Instruct",
|
| 104 |
-
# dtype=torch.bfloat16,
|
| 105 |
-
# attn_implementation="flash_attention_2",
|
| 106 |
-
# device_map="auto",
|
| 107 |
-
# )
|
| 108 |
-
|
| 109 |
-
processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-4B-Instruct")
|
| 110 |
|
| 111 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 112 |
{
|
| 113 |
-
|
| 114 |
-
|
| 115 |
-
{
|
| 116 |
-
"type": "image",
|
| 117 |
-
"image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
|
| 118 |
-
},
|
| 119 |
-
{"type": "text", "text": "Describe this image."},
|
| 120 |
-
],
|
| 121 |
}
|
| 122 |
-
]
|
| 123 |
-
|
| 124 |
-
# Preparation for inference
|
| 125 |
-
inputs = processor.apply_chat_template(
|
| 126 |
-
messages,
|
| 127 |
-
tokenize=True,
|
| 128 |
-
add_generation_prompt=True,
|
| 129 |
-
return_dict=True,
|
| 130 |
-
return_tensors="pt"
|
| 131 |
-
)
|
| 132 |
-
inputs = inputs.to(model.device)
|
| 133 |
-
|
| 134 |
-
# Inference: Generation of the output
|
| 135 |
-
generated_ids = model.generate(**inputs, max_new_tokens=128)
|
| 136 |
-
generated_ids_trimmed = [
|
| 137 |
-
out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
|
| 138 |
-
]
|
| 139 |
-
output_text = processor.batch_decode(
|
| 140 |
-
generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
|
| 141 |
-
)
|
| 142 |
-
print(output_text)
|
| 143 |
```
|
| 144 |
|
| 145 |
-
|
| 146 |
-
#### VL
|
| 147 |
-
```bash
|
| 148 |
-
export greedy='false'
|
| 149 |
-
export top_p=0.8
|
| 150 |
-
export top_k=20
|
| 151 |
-
export temperature=0.7
|
| 152 |
-
export repetition_penalty=1.0
|
| 153 |
-
export presence_penalty=1.5
|
| 154 |
-
export out_seq_length=16384
|
| 155 |
-
```
|
| 156 |
|
| 157 |
-
##
|
| 158 |
-
```bash
|
| 159 |
-
export greedy='false'
|
| 160 |
-
export top_p=1.0
|
| 161 |
-
export top_k=40
|
| 162 |
-
export repetition_penalty=1.0
|
| 163 |
-
export presence_penalty=2.0
|
| 164 |
-
export temperature=1.0
|
| 165 |
-
export out_seq_length=32768
|
| 166 |
-
```
|
| 167 |
|
|
|
|
| 168 |
|
| 169 |
-
|
| 170 |
|
| 171 |
-
|
| 172 |
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
|
| 178 |
-
eprint={2505.09388},
|
| 179 |
-
archivePrefix={arXiv},
|
| 180 |
-
primaryClass={cs.CL},
|
| 181 |
-
url={https://arxiv.org/abs/2505.09388},
|
| 182 |
-
}
|
| 183 |
|
| 184 |
-
|
| 185 |
-
title={Qwen2.5-VL Technical Report},
|
| 186 |
-
author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
|
| 187 |
-
journal={arXiv preprint arXiv:2502.13923},
|
| 188 |
-
year={2025}
|
| 189 |
-
}
|
| 190 |
|
| 191 |
-
|
| 192 |
-
title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
|
| 193 |
-
author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
|
| 194 |
-
journal={arXiv preprint arXiv:2409.12191},
|
| 195 |
-
year={2024}
|
| 196 |
-
}
|
| 197 |
|
| 198 |
-
|
| 199 |
-
title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
|
| 200 |
-
author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
|
| 201 |
-
journal={arXiv preprint arXiv:2308.12966},
|
| 202 |
-
year={2023}
|
| 203 |
-
}
|
| 204 |
-
```
|
|
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
|
|
|
| 3 |
library_name: transformers
|
| 4 |
+
pipeline_tag: image-text-to-text
|
| 5 |
+
base_model: Qwen/Qwen3-VL-4B-Instruct
|
| 6 |
+
base_model_relation: finetune
|
| 7 |
+
model_name: mJev-Qwen3-VL-4B-RLCD
|
| 8 |
+
tags:
|
| 9 |
+
- mjev
|
| 10 |
+
- multimodal
|
| 11 |
+
- decision-making
|
| 12 |
+
- reinforcement-learning
|
| 13 |
+
- grpo
|
| 14 |
+
- rlcd
|
| 15 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 16 |
|
| 17 |
+
# mJev-Qwen3-VL-4B-RLCD
|
| 18 |
|
| 19 |
+
**Jev, with senses. Multimodal context in, explicit decisions out.**
|
| 20 |
|
| 21 |
+
[GitHub](https://github.com/SoMarkAI/mJev) · [Evaluation dataset](https://huggingface.co/datasets/Immortal-Zhang/mJev-Compositional-VQA) · [Deployment guide](https://github.com/SoMarkAI/mJev/blob/main/docs/models.md)
|
| 22 |
|
| 23 |
+
mJev-Qwen3-VL-4B-RLCD is SoMark's 4B multimodal decision model, fine-tuned with GRPO from [Qwen3-VL-4B-Instruct](https://huggingface.co/Qwen/Qwen3-VL-4B-Instruct). It is designed to select among explicit candidates given visual context and a question.
|
|
|
|
|
|
|
| 24 |
|
| 25 |
+
With the mJev runtime, each question returns a selected answer, candidate probabilities and raw logits. Multiple questions can share the same context, with optional prefix-cache reuse. This repository contains the full fine-tuned weights and processor/tokenizer files; the inference runtime lives in the [mJev code repository](https://github.com/SoMarkAI/mJev).
|
| 26 |
|
| 27 |
+
## Model at a glance
|
| 28 |
|
| 29 |
+
| Property | Details |
|
| 30 |
+
| --- | --- |
|
| 31 |
+
| Developer | SoMark |
|
| 32 |
+
| Model family | Qwen3-VL, 4B |
|
| 33 |
+
| Task | Multimodal probabilistic decision making |
|
| 34 |
+
| Inputs | Images or video with text questions and candidate choices |
|
| 35 |
+
| Decision interface | Candidate-label logits, normalized candidate probabilities and an argmax decision |
|
| 36 |
+
| Post-training | GRPO with target-probability-weighted correctness rewards |
|
| 37 |
+
| Weight format | Full model, BF16 Safetensors |
|
| 38 |
+
| License | Apache 2.0 |
|
| 39 |
|
| 40 |
+
## Evaluation
|
| 41 |
|
| 42 |
+
On a **195-question evaluation subset** of [mJev-Compositional-VQA](https://huggingface.co/datasets/Immortal-Zhang/mJev-Compositional-VQA), GRPO fine-tuning improves accuracy from **77.95% to 80.00% (+2.05 percentage points)**, answering four additional questions correctly.
|
| 43 |
|
| 44 |
+
| Model | Correct / total | Accuracy |
|
| 45 |
+
| --- | ---: | ---: |
|
| 46 |
+
| Qwen3-VL-4B-Instruct — before GRPO | 152 / 195 | 77.95% |
|
| 47 |
+
| **mJev-Qwen3-VL-4B-RLCD — after GRPO** | **156 / 195** | **80.00%** |
|
| 48 |
|
| 49 |
+
Both models were evaluated on the same questions, held out from RL training. Accuracy is the number of correct answers divided by the total number of questions. These results describe this evaluation subset; broader benchmark performance has not been established by this comparison.
|
|
|
|
|
|
|
|
|
|
|
|
|
| 50 |
|
| 51 |
+
## Quick start
|
| 52 |
|
| 53 |
+
Use the mJev runtime to obtain candidate probabilities and decisions. The HF path scores candidate labels with a model forward pass; it does not require generating a free-form answer.
|
|
|
|
| 54 |
|
| 55 |
+
Prepare Linux, Python 3.11+, a compatible NVIDIA GPU environment and system FFmpeg. Install the runtime and download this model:
|
| 56 |
|
| 57 |
+
```bash
|
| 58 |
+
git clone https://github.com/SoMarkAI/mJev.git
|
| 59 |
+
cd mJev
|
| 60 |
+
python3 -m venv .venv
|
| 61 |
+
source .venv/bin/activate
|
| 62 |
+
python -m pip install torchcodec==0.11.0+cpu --index-url https://download.pytorch.org/whl/cpu
|
| 63 |
+
python -m pip install -e '.[hf-vl]' huggingface_hub
|
| 64 |
+
|
| 65 |
+
export MODEL_DIR="$HOME/models/mJev-Qwen3-VL-4B-RLCD"
|
| 66 |
+
hf download SoMarkAI/mJev-Qwen3-VL-4B-RLCD --local-dir "$MODEL_DIR"
|
| 67 |
+
|
| 68 |
+
CUDA_VISIBLE_DEVICES=0 python demo_hf.py \
|
| 69 |
+
--model "$MODEL_DIR" \
|
| 70 |
+
--input examples/motion-demo/input.json \
|
| 71 |
+
--mode causal --numerics stable --projection full \
|
| 72 |
+
--prefix-cache --question-batch-size 3 \
|
| 73 |
+
--output outputs/mjev-decisions.json
|
| 74 |
```
|
| 75 |
|
| 76 |
+
The example asks three questions about a project-created video. Inspect `outputs/mjev-decisions.json` for decisions and candidate scores. For your own image, create an input JSON file with this structure and pass it to `--input`:
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 77 |
|
| 78 |
+
```json
|
| 79 |
+
{
|
| 80 |
+
"image": "your-image.png",
|
| 81 |
+
"context": "Inspect the supplied picture.",
|
| 82 |
+
"questions": [
|
| 83 |
{
|
| 84 |
+
"question": "Which object is visible?",
|
| 85 |
+
"candidates": ["A bicycle", "A car", "A bus"]
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 86 |
}
|
| 87 |
+
]
|
| 88 |
+
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 89 |
```
|
| 90 |
|
| 91 |
+
Media paths are relative to the input JSON file. See the [HF guide](https://github.com/SoMarkAI/mJev/blob/main/docs/hf.md) for the Python API, video inputs and memory settings. The weights retain the standard Qwen3-VL architecture and can also be loaded with Transformers; use the mJev runtime for the candidate-scoring interface described here.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 92 |
|
| 93 |
+
## Training and reward
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 94 |
|
| 95 |
+
Before RL, a frozen candidate scorer records the probability `p_target` assigned to the ground-truth option. Each sampled label receives **+p_target when correct** and **-p_target when incorrect or invalid**. Rewards are bounded in [-1, 1], and examples with higher target probabilities produce stronger training signals.
|
| 96 |
|
| 97 |
+
GRPO rollouts are constrained to a single candidate label, with no separate format reward. Reward scaling is disabled to preserve the target-probability weighting. A separate KL penalty limits drift from the reference model. Training updates the language model while keeping the vision tower and aligner frozen.
|
| 98 |
|
| 99 |
+
## Use and limitations
|
| 100 |
|
| 101 |
+
- Intended for visual question answering and decision workflows with explicitly defined candidate sets.
|
| 102 |
+
- Candidate probabilities are relative to the supplied choices, not calibrated confidence estimates. Candidate wording, order and coverage can affect decisions.
|
| 103 |
+
- This release supports visual inputs; it does not add audio support. The reported RL evaluation covers image questions, not video or audio benchmarks.
|
| 104 |
+
- The 195-question comparison is an initial evaluation. It does not establish broad reasoning gains or statistical significance.
|
| 105 |
+
- Input length, image resolution, video sampling and question batching affect memory use and latency. See the runtime documentation for supported settings.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 106 |
|
| 107 |
+
## License and acknowledgments
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 108 |
|
| 109 |
+
Released under [Apache 2.0](https://www.apache.org/licenses/LICENSE-2.0). mJev builds on Qwen3-VL-4B-Instruct; we thank the Qwen team for the base model and the Jev project for the decision-oriented interface inspiration. Evaluation data retains its own license and terms.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 110 |
|
| 111 |
+
For issues, implementation details and contributions, visit [SoMarkAI/mJev](https://github.com/SoMarkAI/mJev).
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|