**Everyone says Pascal died in the 90s.** Meanwhile, this Free Pascal library runs GPT-style transformers, Mixture-of-Experts, RWKV, xLSTM, spiking neurons, and normalizing flows, natively, with no Python nor CUDA lock-in.
These models have been tested and they run in pure Free Pascal: * HuggingFaceTB/SmolLM2-1.7B-Instruct * Qwen/Qwen2.5-{0.5B,1.5B,3B,7B,14B,32B}-Instruct * Qwen/Qwen3-0.6B * Qwen/Qwen3-30B-A3B-Thinking-2507 * TinyLlama/TinyLlama-1.1B-Chat-v1.0 * mistralai/Mistral-7B-Instruct-v0.3 * microsoft/Phi-3-mini-4k-instruct * allenai/OLMoE-1B-7B-0125-Instruct * state-spaces/mamba-130m-hf * openai-community/gpt2
PHP-Code-Large is a large-scale corpus of PHP source code comprising more than 12 million lines of PHP code. The dataset is designed to support research in large language model (LLM) pretraining, code intelligence, software engineering automation, and static program analysis for the PHP ecosystem.
By providing a high-volume, language-specific corpus, PHP-Code-Large enables systematic experimentation in PHP-focused model training, domain adaptation, and downstream code understanding tasks.
PHP-Code-Large addresses the need for a dedicated PHP-only dataset at substantial scale, enabling focused research across backend systems, CMS platforms, APIs, and full-stack PHP environments.
โก Speaking is faster than typing - BPSA - Powerful Open Source Agentic Coding Tool with Voice Support - a smolagents fork - Interactive REPL CLI Tool - New Voice Support! โฟ Accessibility โ It's a huge benefit for people with mobility issues, dyslexia, or other conditions that make typing difficult. ๐๏ธ Hands-free operation โ You can dictate while doing other things, like looking at documents or moving around.
๐ข I will create your README.md file 4 you 4 free
I am currently testing an open source prototype that writes/updates README.md files for projects with up to 10k source code lines.
If you have an open source project needing a new README file on github, just reply to this post with your project URL. Your project will be used in my testing. If all is good in the testing, I'll send you a pull request via github with the updated README.md.
No submitted source code will be used for model training.
All computer languages are accepted including pascal, java, cobol, fortran, lisp, โฆ
I will create READMEs only for the first few requests. The testing is available only to open source projects.
โจ TODAY: DeepSeek unveiled Flash MLA: a efficient MLA decoding kernel for NVIDIA Hopper GPUs, optimized for variable-length sequences. https://github.com/deepseek-ai/FlashMLA
Moonshot AI introduces Moonlight: a 3B/16B MoE trained on 5.7T tokens using Muon, pushing the Pareto frontier with fewer FLOPs. moonshotai/Moonlight-16B-A3B
Huge disappointment to Claude Sonnet 3.7 ๐ Big performance regression. Worse than the June version in 2024. ๐ onekq-ai/WebApp1K-models-leaderboard
I'm sure though this version improves on something, only not the thing my leaderboard measures. This proves the point that no model can be the best on everything.
๐ข Old Research Alert: Making Computer Vision Models Smaller & Smarter!
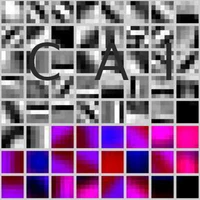
Years ago, I coded an optimization in the first layers of a convolutional neural network (computer vision) and ended never posting here. The optimization decreases the number of parameters while increasing accuracy. The optimization relies in separating (branching) chromatic and achromatic information through the layers of a neural network.
In the case that you run into any roadblock at modifying an existing model with this optimization so you can train the optimized model from scratch, please feel free to ask for help.